AI Brand Activation Photo Booth: Setup, Speed and Print
A crowded trade show floor punishes slow activations. When a guest waits too long for a result, the line stalls, the energy drops, and a branded moment turns into a bottleneck. An AI brand activation photo booth only works when three technical systems hold together at the same time: structural image control, facial preservation, and an output path that finishes before the guest walks away.
That is the difference between a booth that entertains for ten minutes and one that produces measurable campaign assets for the length of the show.
What an AI Brand Activation Booth Actually Does
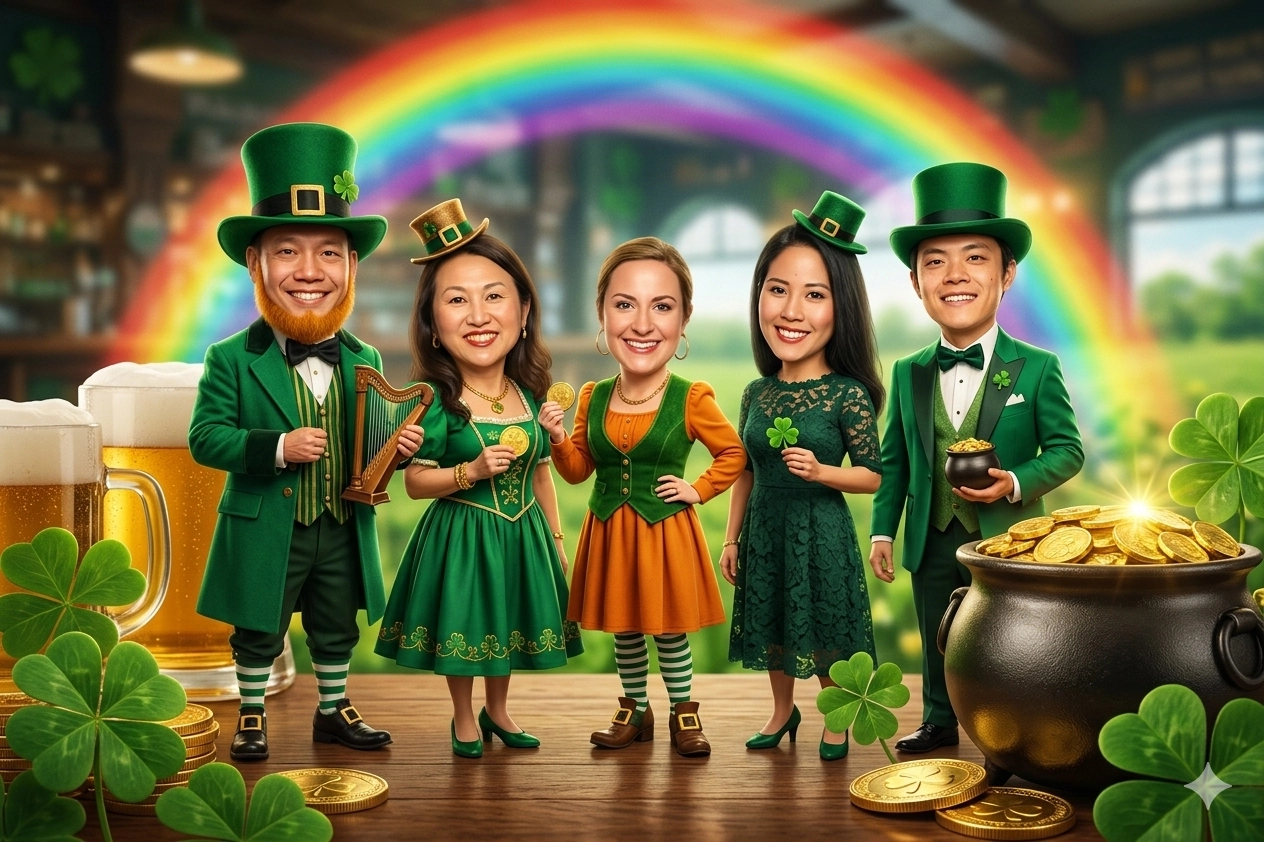
An AI photo booth captures a guest photo, passes that image through a generation pipeline, and returns a branded result built around the campaign rather than a generic filter. The finished asset can be a character, an avatar, a styled portrait, or a themed scene that matches a brand’s visual identity. Alongside the image, the booth can capture guest data, which turns a fun stop on the floor into a lead source.
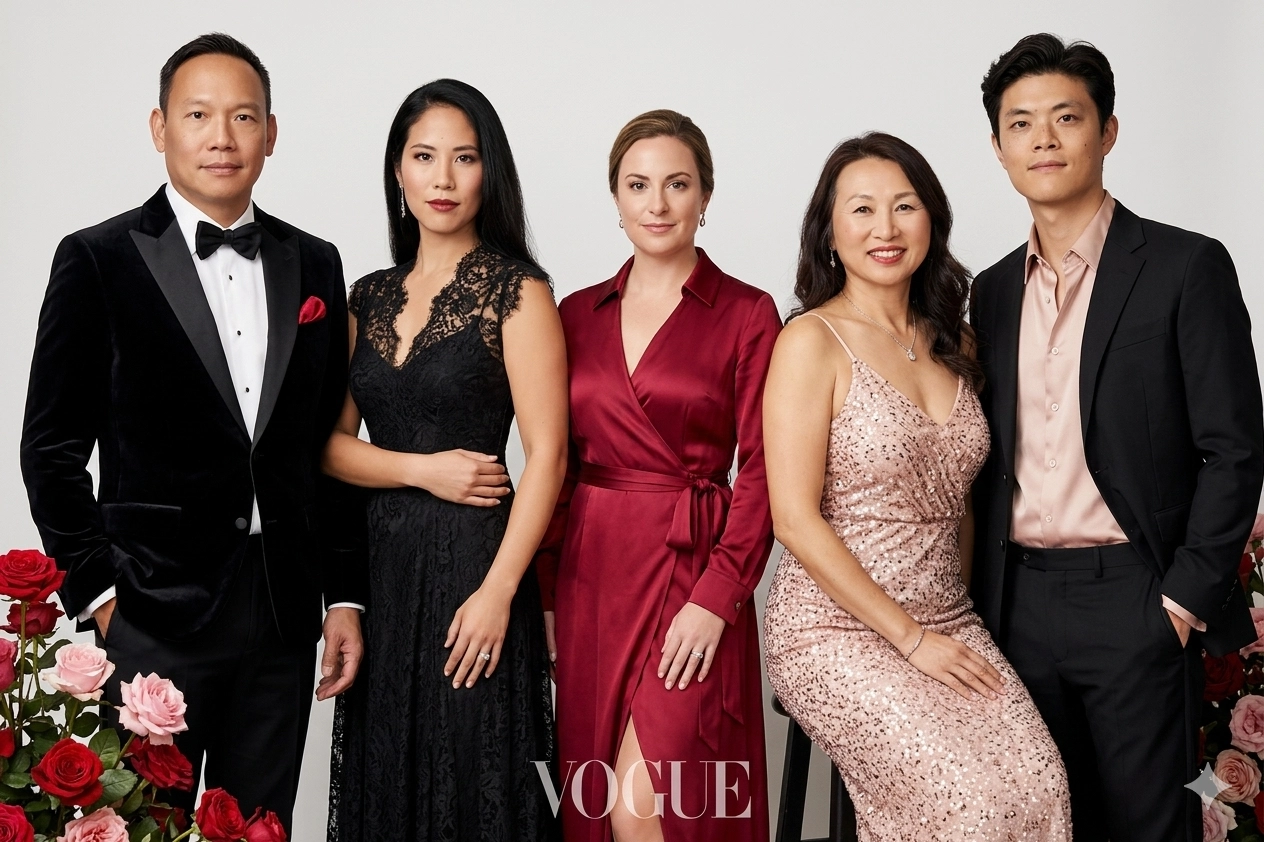
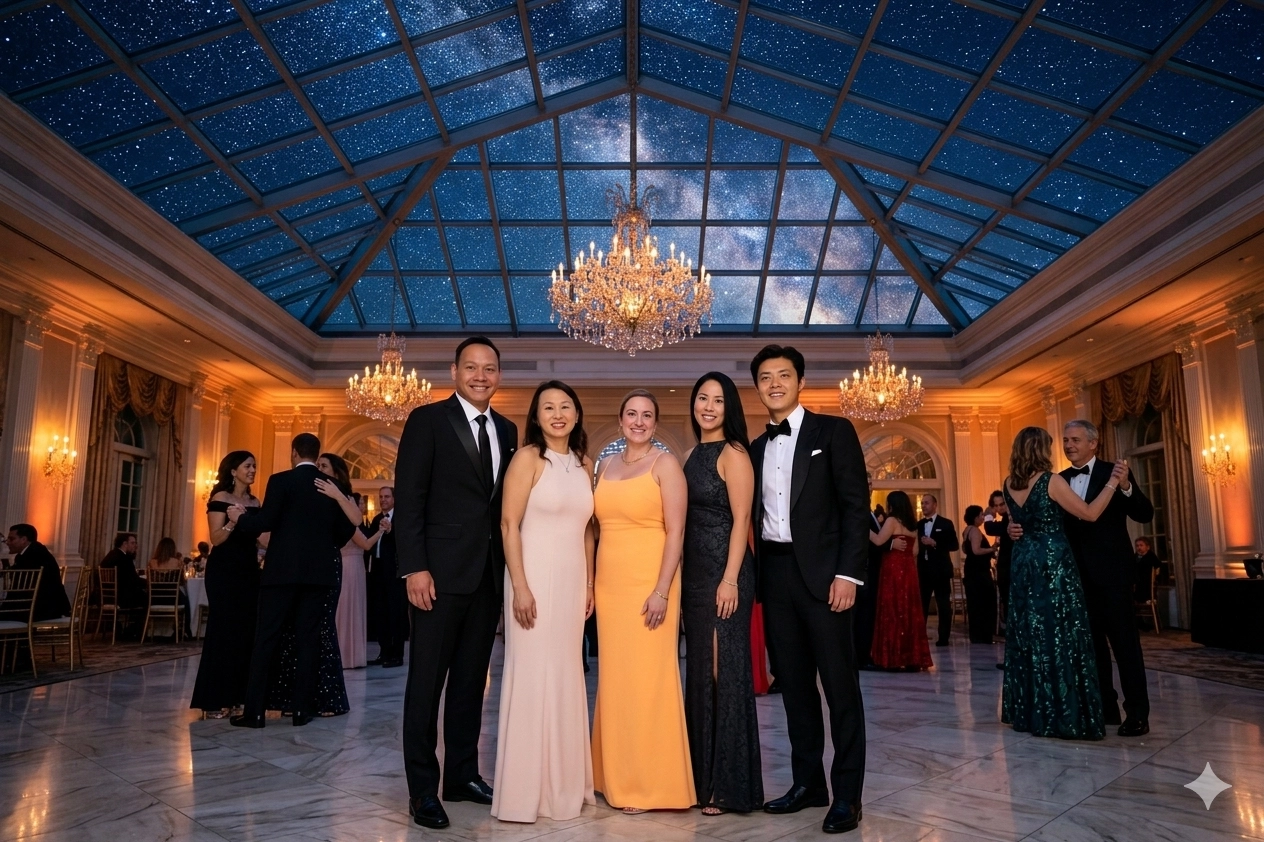
For agencies and brand teams, that combination matters more than the novelty. The photo is the hook. The shareable asset and the contact record are the return on the activation budget. Brand-trained AI styles, themed campaign worlds, lead capture, and reporting are what separate a photo booth rental from a marketing channel. Common formats include branded character or avatar creators, glamour and red-carpet filters, and style transfer booths that place a guest inside a campaign world.
The ControlNet Layer and Structural Control
Diffusion-based image generation starts from noise and follows a prompt. Left alone, the model decides pose, framing, and composition on its own, which means the same guest photographed twice can produce two completely different results. ControlNet adds a conditioning layer on top of the base model. It reads structural maps from the source photo, such as pose, depth, and edge data, and forces the generation to respect them.
In a live activation, that is what keeps every output on brand and consistent. The guest stays in the same frame position. The composition holds from the first person in line to the five hundredth. Prompt instructions and identity instructions are applied on one side of the pipeline, and structural conditioning is applied on the other, so the render cannot drift away from the capture the booth actually recorded.
Facial Preservation Through Strict Weighting
Identity is the part guests notice first, and it is the part that fails loudest. Strict weights are set within the generation pipeline so the finished image matches the guest’s actual face instead of substituting a generic, slightly wrong replacement. Weighting high enough to hold the face, but balanced enough to allow the stylistic layer to read, is the tuning job that separates a professional build from a demo.
Before doors open, the practical test is simple. Capture staff members under the real event lighting, run them through the pipeline, and check whether a colleague would recognise each person without being told who it is.
Why Structural Control Beats Prompt-Only Generation
A prompt-only build can look impressive in a single test image, then fall apart across a queue because nothing anchors the pose. Adding a structural conditioning layer reduces retries, which reduces reprints, which protects throughput. It also makes the visual output predictable enough for a brand team to approve in advance rather than hope for on the day.
Technical layer | On-site requirement | What fails without it |
|---|---|---|
Identity preservation | Strict weighting in the generation pipeline | Generic faces and guest complaints |
Structural control | ControlNet conditioning from the source capture | Inconsistent framing across the queue |
Throughput | Local GPU hardware or high-speed cloud pipeline | Lines that stall past the 30 second mark |
Capture quality | Neutral, high-CRI continuous or strobe lighting | Muddy source images and weak renders |
Output | On-site dye-sub printing plus digital delivery | Guests leaving with nothing in hand |
Processing Speed and Line Flow
Completed images need to arrive in under 30 seconds per guest to keep a line moving without visible friction. That target is achievable with local GPU hardware running on site, or with a high-speed cloud pipeline when the venue network can carry the upload and download load. Cloud rendering offers flexibility. Local rendering removes dependence on venue Wi-Fi, which is often the weakest link in an exhibition hall.
Whatever the architecture, the guest experience should feel like a photo booth, not a render farm. A progress indicator that shows the generation working keeps attention on the screen rather than on the wait. When throughput is designed correctly, the queue becomes part of the activation instead of a reason people keep walking.
Lighting Infrastructure for Clean Source Capture
The model can only work with the source image it receives. Neutral, high-CRI continuous lighting or a strobe setup is required on site so the captured frame is clean enough to feed the pipeline properly. High colour rendering index lighting keeps skin tones accurate, which in turn gives the identity layer more reliable information to preserve.
Mixed lighting is the usual culprit behind inconsistent output. Coloured ambient spill from a neighbouring booth, overhead convention lighting, and an on-camera flash fighting each other will produce source images that vary guest by guest. Controlling the capture environment is cheaper than trying to correct for it inside the generation pipeline.
On-Site Dye-Sub Print and Digital Delivery
Dye-sublimation printing gives the activation a physical takeaway. A dye-sub printer on site produces a finished print within the flow of the booth, which matters because a guest holding something tangible becomes a walking advertisement on the show floor. Printed output also extends the life of the campaign past the event itself.
Digital delivery runs alongside it. Guests receive the file by email, text, or a QR code, which is what allows the shareable asset to travel into social feeds. The print is for the person. The digital file is for their network. Designing the delivery step around both channels is what makes the activation spread beyond the room.
Master AI Prompt Template Structure
When a booth is built into custom software, a consistent prompt structure keeps visual quality stable across different guests, different operators, and different lighting conditions. The template should carry the same blocks every time, with only the subject data changing.
-
Project context: the campaign, the event, and the intended use of the image.
-
Subject instruction: preserve the identity and features of the person in the source frame.
-
Style layer: the brand-trained visual style, palette, or themed world to apply.
-
Output specification: aspect ratio, resolution, and format for both print and digital delivery.
-
Negative instructions: what the render must avoid, such as altered facial structure or off-brand elements.
Locking these blocks removes operator guesswork. Anyone running the booth produces the same quality of output, and the brand team sees a consistent asset across the full run of the event.
Brand Trained Styles, Lead Capture and Reporting
Brand-trained AI styles and themed campaign worlds are what connect the experience to the marketing objective. Training the style on the brand’s own visual language means the generated content reads as campaign material rather than a random filter. The same booth can capture guest data at the point of delivery, then report on it afterwards so the activation produces numbers alongside photos.
Pre-Event Checklist for Los Angeles and Orange County Activations
-
Confirm venue power access and a dedicated circuit for GPU hardware and printers.
-
Map the queue path and floor space before the booth footprint is finalised.
-
Test network stability, or plan for fully local rendering.
-
Approve brand assets, style references, and negative prompts in advance.
-
Run a live capture test under the actual event lighting before guests arrive.
Frequently Asked Questions
How long does an AI photo booth take to produce an image?
A well-configured booth delivers a completed image in under 30 seconds per guest, using local GPU hardware or a high-speed cloud pipeline. That pace is what keeps a line flowing at a trade show or product launch. Anything slower creates queue pressure and reduces the number of people who can move through the activation during peak hours.
Will the AI change how a guest looks?
It should not change facial identity. Strict weights within the generation pipeline are set so the finished image matches the guest accurately, and the styling layer is applied around those features rather than over them. Reviewing sample renders before the event is the practical way to confirm the balance is correct for a specific campaign.
Do guests receive a physical print as well as a digital file?
Both are usually part of the build. On-site dye-sublimation printing produces a finished print during the booth visit, while a digital copy is delivered by email, text, or QR code for sharing. The print acts as an on-floor takeaway and the digital file extends the campaign into social channels after the event ends.
Why does lighting matter for AI image quality?
The generation pipeline can only work with the source image it receives. Neutral, high-CRI continuous lighting or a strobe setup produces clean, colour-accurate captures that the model can render faithfully. Mixed or coloured ambient light creates inconsistent source frames, which leads to uneven output quality from one guest to the next across the same event.
Does an AI photo booth capture lead data?
It can. Alongside generating the branded asset, an AI booth can collect guest contact details at the point of delivery and report on that activity for the brand or agency afterwards. That is the feature that turns a photo activation into a measurable marketing channel rather than a standalone entertainment booking on the event floor.
To understand the foundational mechanics behind these activations, you can explore the technical principles of diffusion-based image generation on Wikipedia.
To understand the foundational technology behind these activations, you can explore how diffusion-based image generation functions to transform input data into visual assets.